
I have been tracing a pattern across recent posts…
First, PSTN became the CLI for voice agents, the universal voice interface had already existed for a century, we just had to let agents dial it.
The distribution is existing, and the technology is established and pervasive.
Allow me a brief digression, In a recent podcast Evan Spiegel (CEO and co-founder of Snapchat) spoke about the power of distribution. Anyone using AI can copy and replicate the Snapchat app. But the same cannot be said for distribution; the ecosystem.
When it comes to AI, companies with existing distribution will, or rather should find it easier to achieve success. Think of Apple, Microsoft and others.
Elon Musk purchasing Twitter afforded him exceptional distribution for Xai. Same for OpenAI with their early alliance with Microsoft.
Then, CLI replaced MCP as the natural tool interface, fifty years of Unix tooling already on every machine, no new protocol required.
This is especially the case for AI Agents living on your computer, the CLI becomes a powerful interface to act as a meta-tool for AI Agents.
Then, the IDE became optional, the visual layer was solving human limitations the agent does not have.
There is a fourth move in this sequence, and it is the quietest of them all.
Markdown is becoming the mediation layer between humans, models and machines.
What I mean by mediation layer
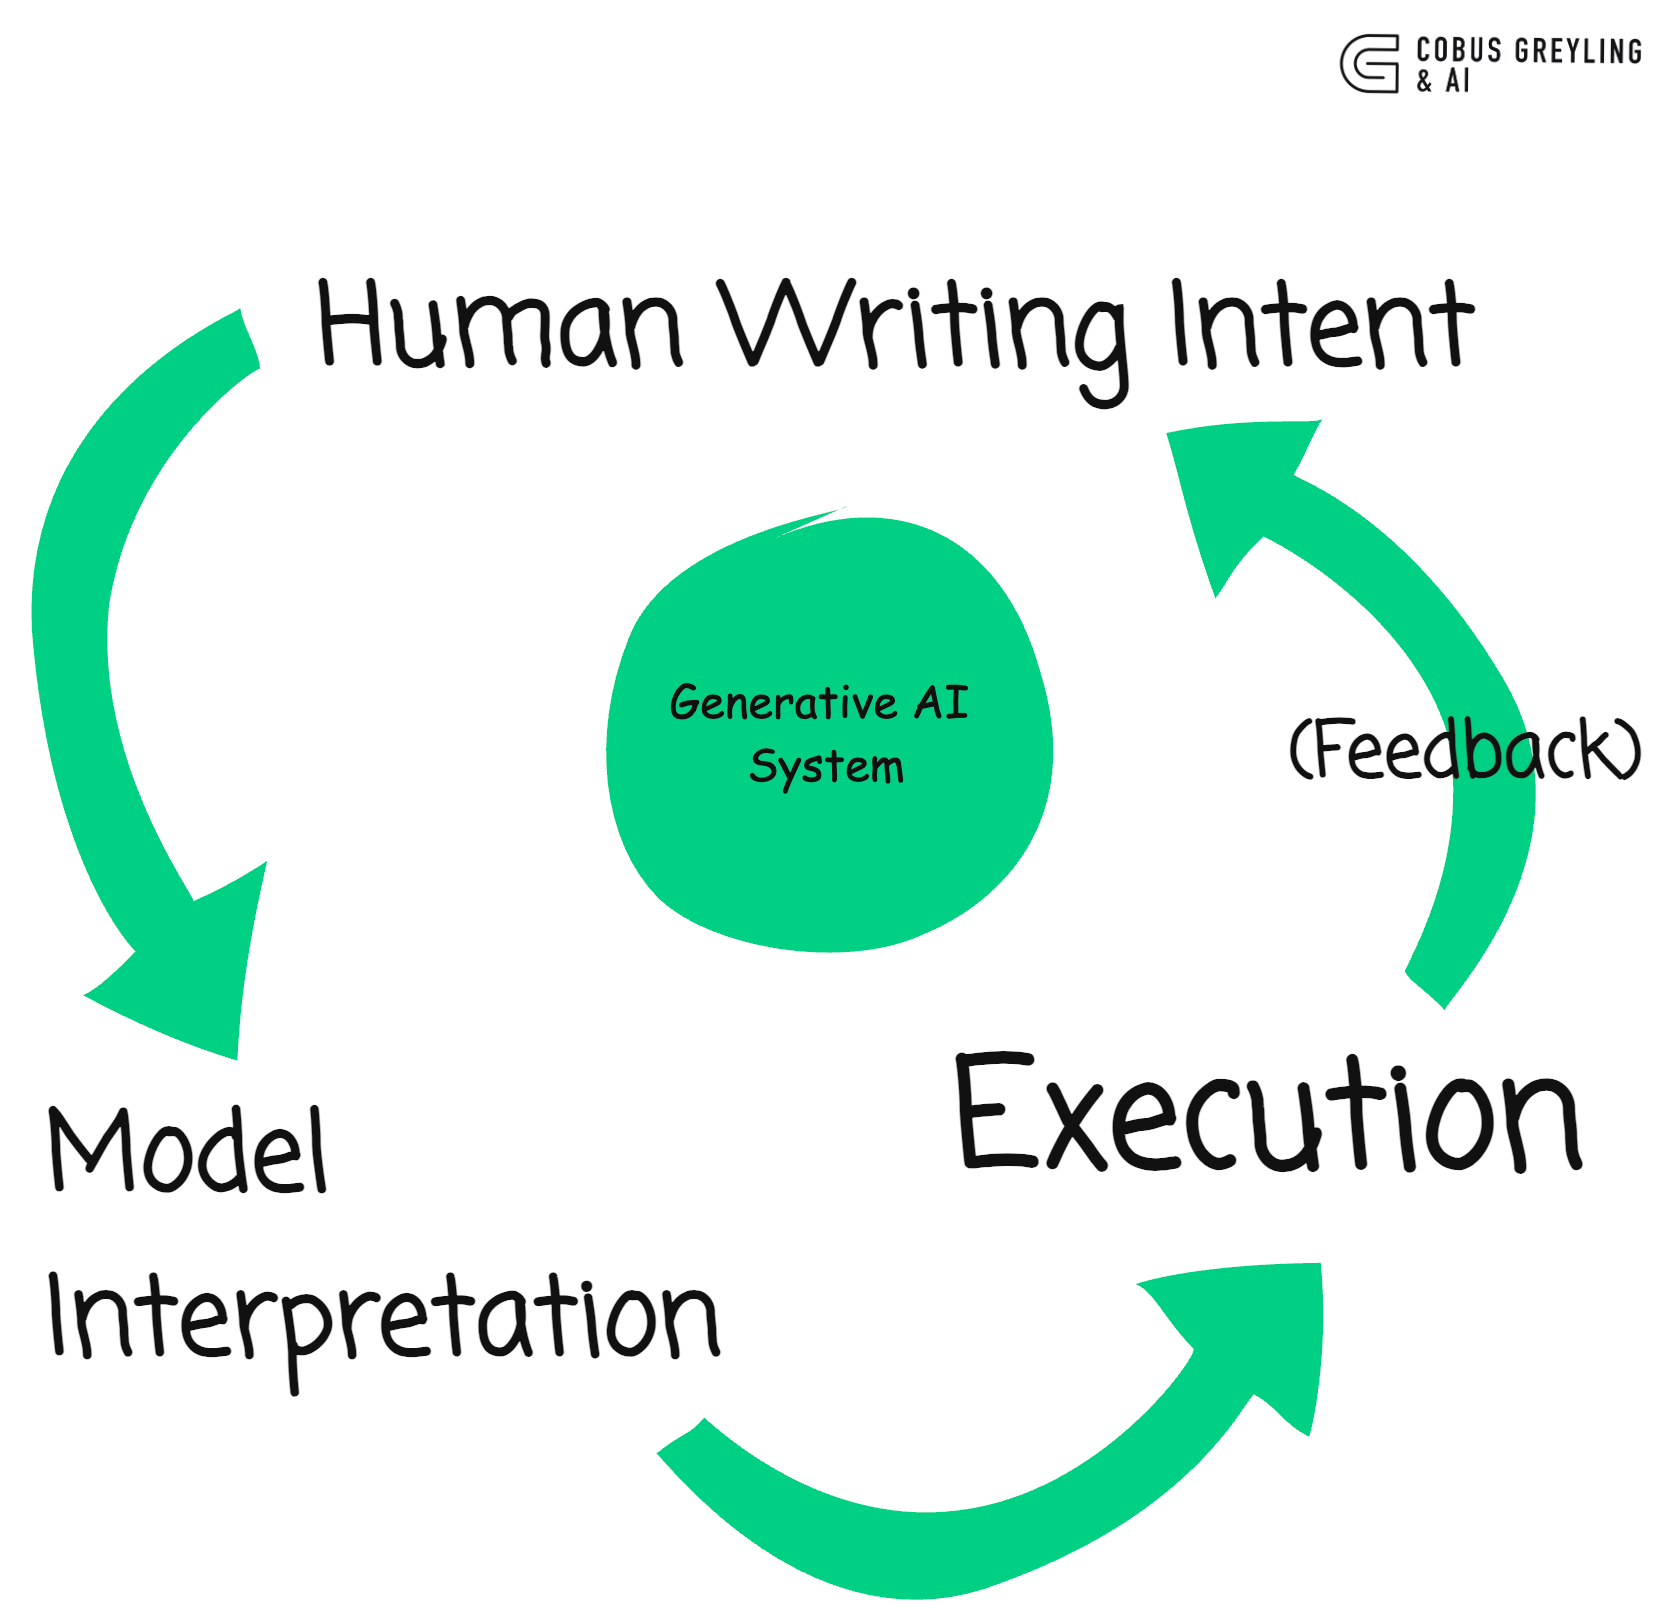
Every agentic system needs a place where three parties meet…
the human writing intent,
the model interpreting it, and
the machine executing it.
Historically that meeting point was a schema.
JSON, YAML, XML…
Each one solved the same problem to some degree in a different syntax…
Give the machine something rigid to parse and give the human a documentation site to read alongside it.
The agent era does not need that split.
The model reads and writes natural text.
The human reads and writes natural text.
The format that sits between them no longer needs to be machine-first.
It needs to be legible to both at once.
That format is markdown.
Markdown advances
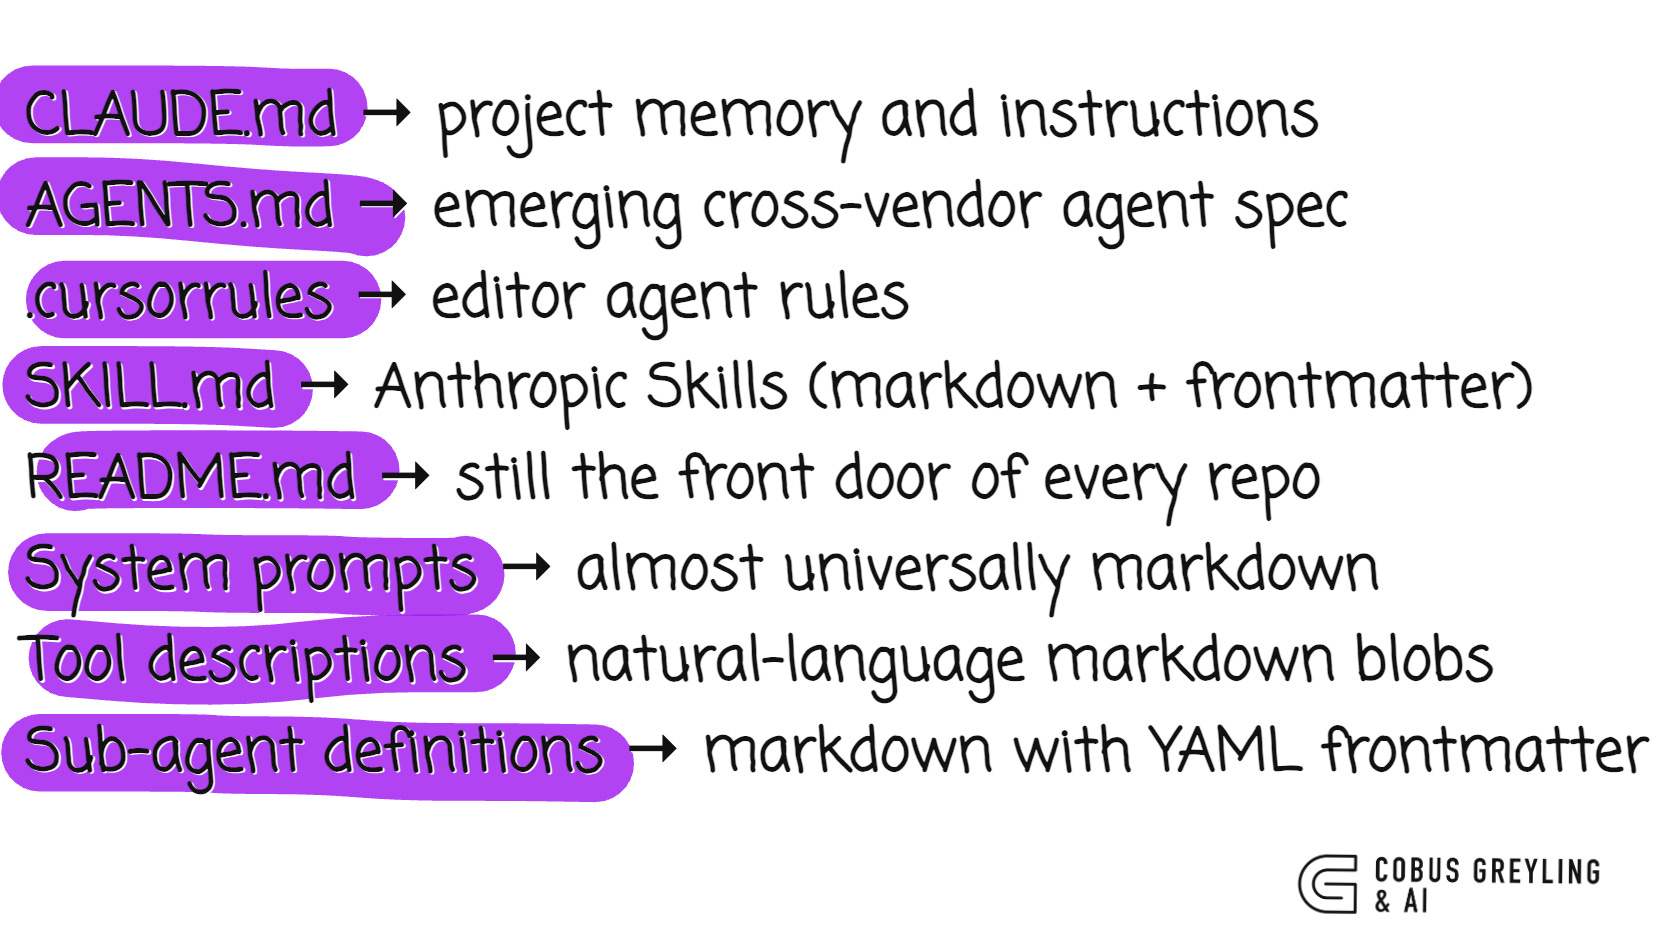
Look at where the new agentic primitives are used...
There is no committee deciding this.
No RFC.
No standards body.
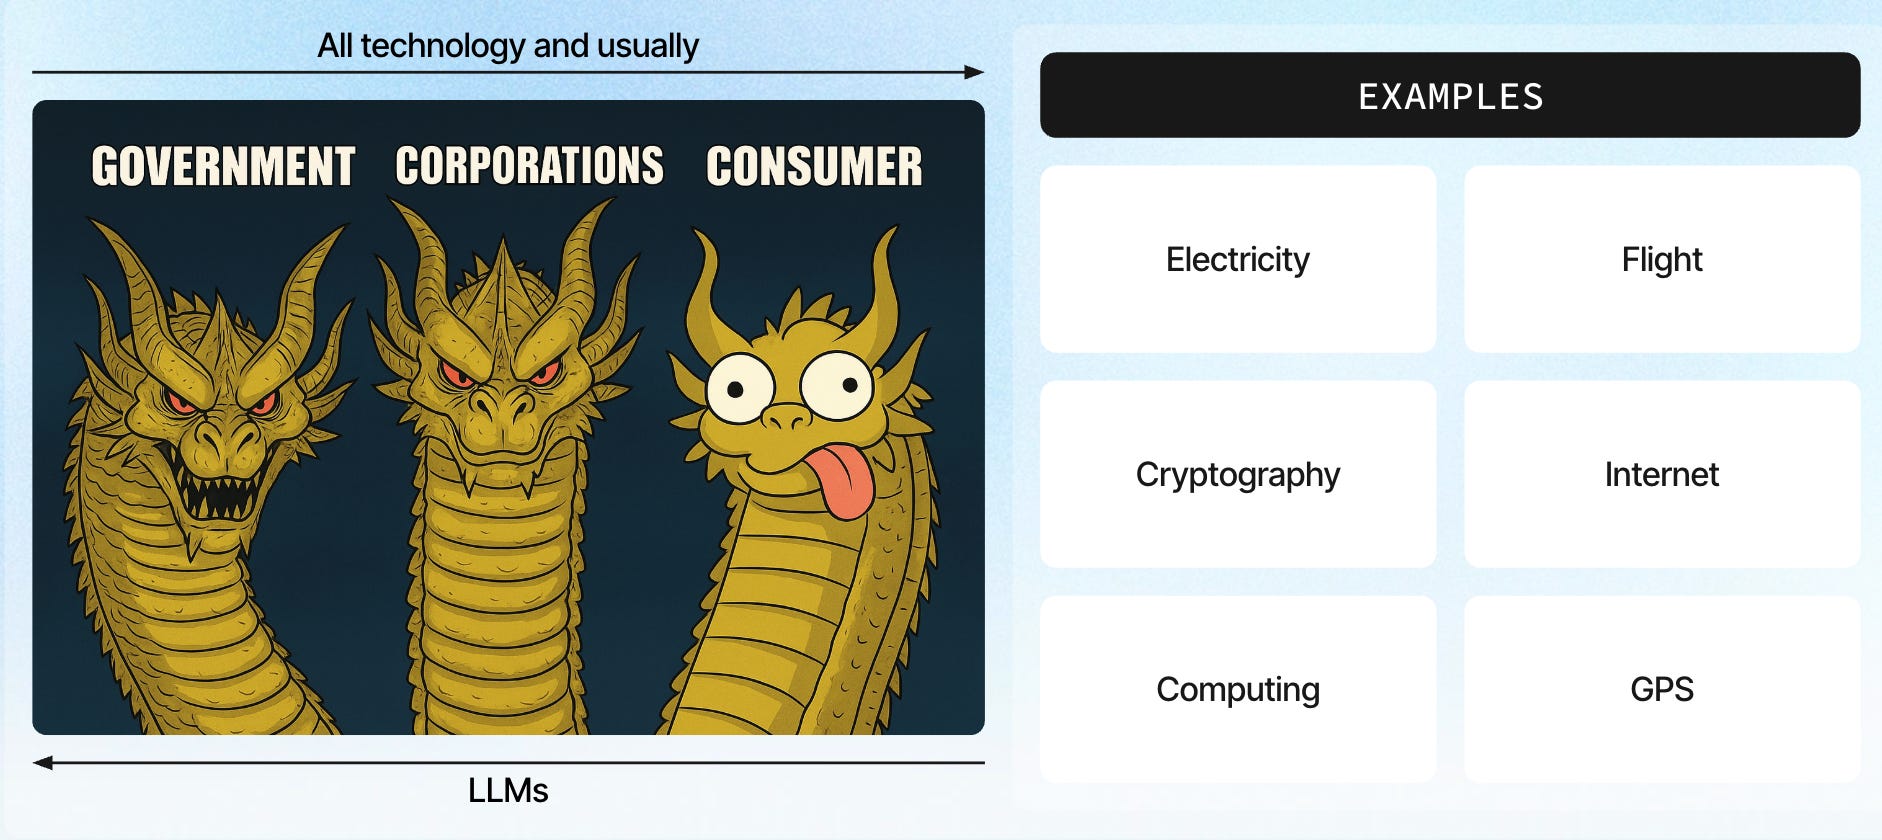
It reminds me of the narrative from Andrej Karpathy…as seen below. The diffusion of world impacting technologies have always taken place from the top down.
Considering the image below, other technologies like electricity, faith, GPS and more was diffused from the top down. Government, corporates and finally consumers.
AI in general, and Generative AI/Language Models in specific inverted this diffusion of technology. The technology adopted by the masses, and the masses are organising themselves around it.
This most probably contribute to the immense speed of innovation and development.
So it is the same with agentic primitives, It just keeps happening…because every team that builds an agentic system arrives at the same answer independently.
There is something beautiful when there is an automatic convergence on an idea or principle. Not because it was orchestrated by a body or institution.
But because it it is genuinely the best approach and idea that have won.
The format that is readable by humans and native to models wins by default.
Markdown & not JSON?
JSON is the obvious counter-argument. It is structured, parseable, machine-validated.
It is what every API has used for twenty years, right?
The problem is that JSON was designed for a world where the consumer was a parser, not a reader.
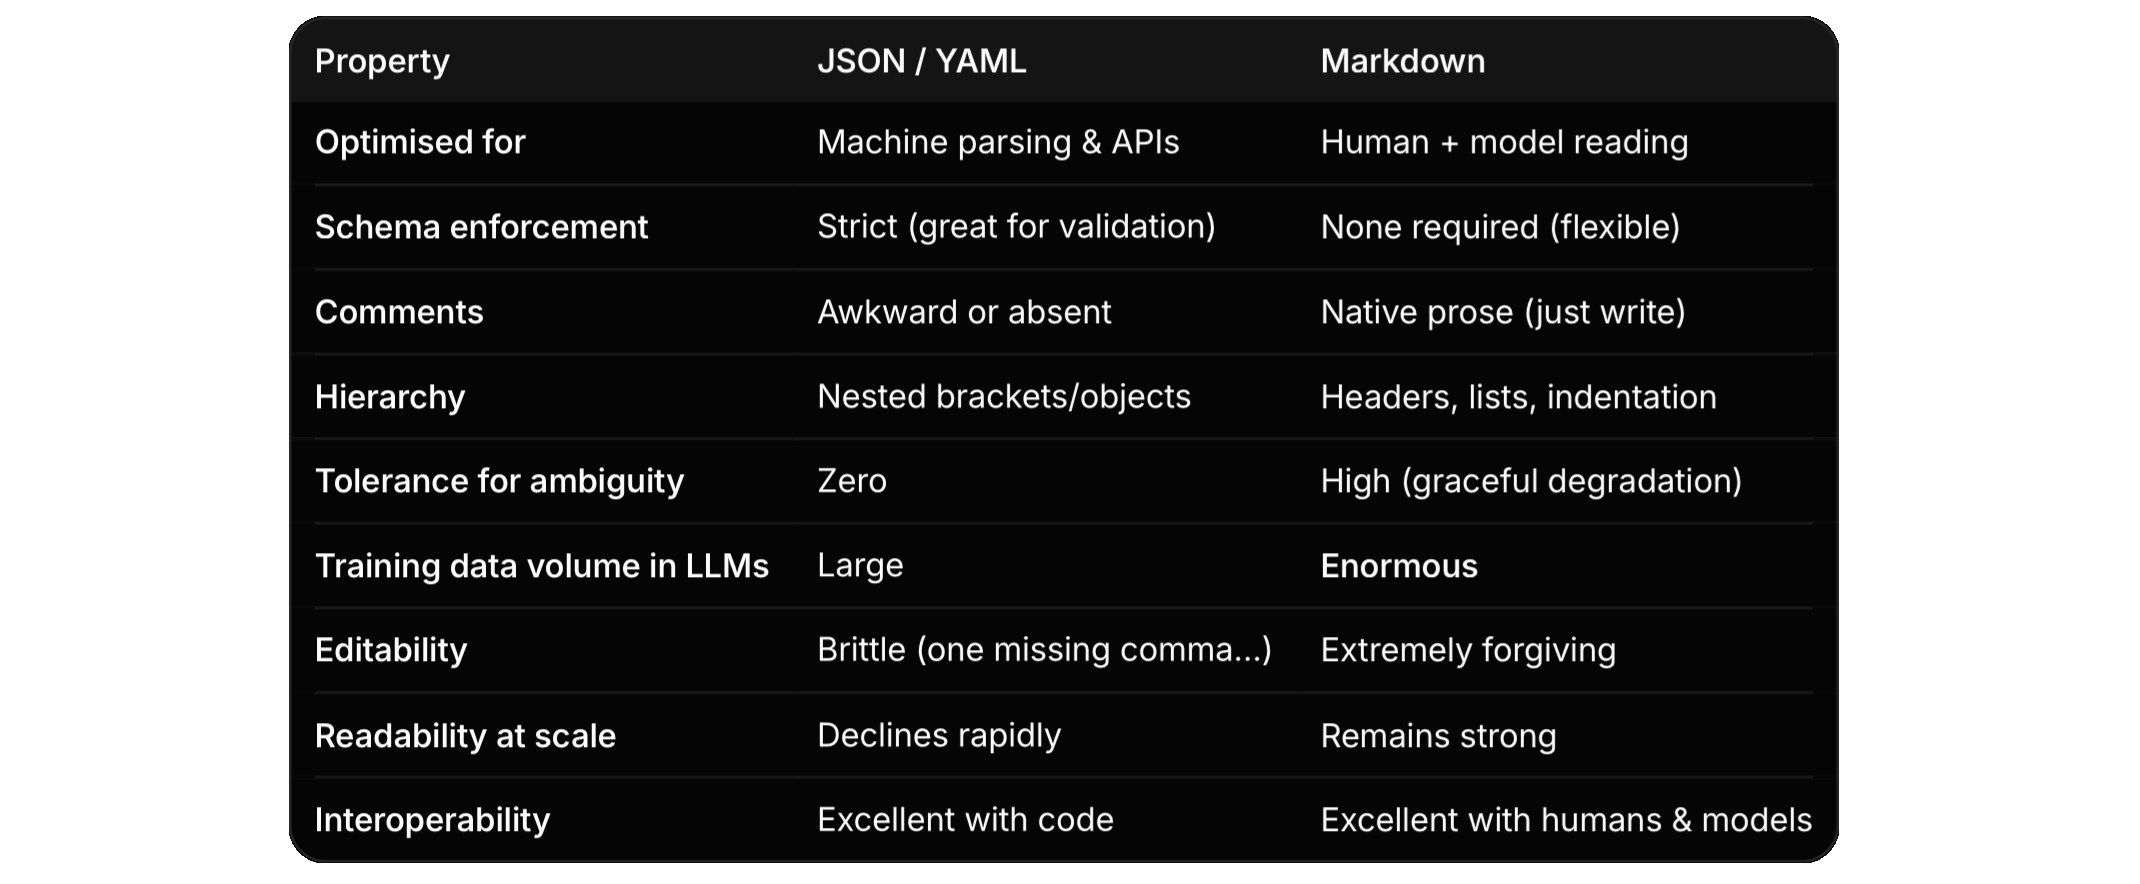
The last row is the one that matters.
LLMs have ingested every README, every blog post, every documentation site, every man page on the open web.
Markdown is not just a format the model can produce, it is a format the model seemingly thinks in.
Ask a model to output structured JSON and it will, but it is doing translation work.
Ask it to output markdown and it is just speaking its native language.
Inversion
Here is what I find interesting...
For thirty years, we built configuration formats by adding rigour.
We started with `.ini` files, moved to XML, then JSON, then YAML, then JSON Schema…
Each step added more structure, more validation, more tooling.
The agentic era is reversing the entire trajectory.
Anthropic Skills are markdown files with a frontmatter block.
Claude Code’s project config is a markdown file.
Sub-agents are markdown files.
It seems like we have spent decades teaching humans to write more structured formats so machines could parse them.
Now we are unwinding it, because the machines learned to read what humans were already writing.
Agent design
If you are building an agentic system in 2026, three practical implications follow, I think.
Stop designing schemas first.
Write the markdown a human would write to brief a teammate.
The model will use it.
If you later need machine validation, add it at the edges, not at the centre.
Treat markdown files as first-class runtime artefacts.
This is something Anthropic is very good at…
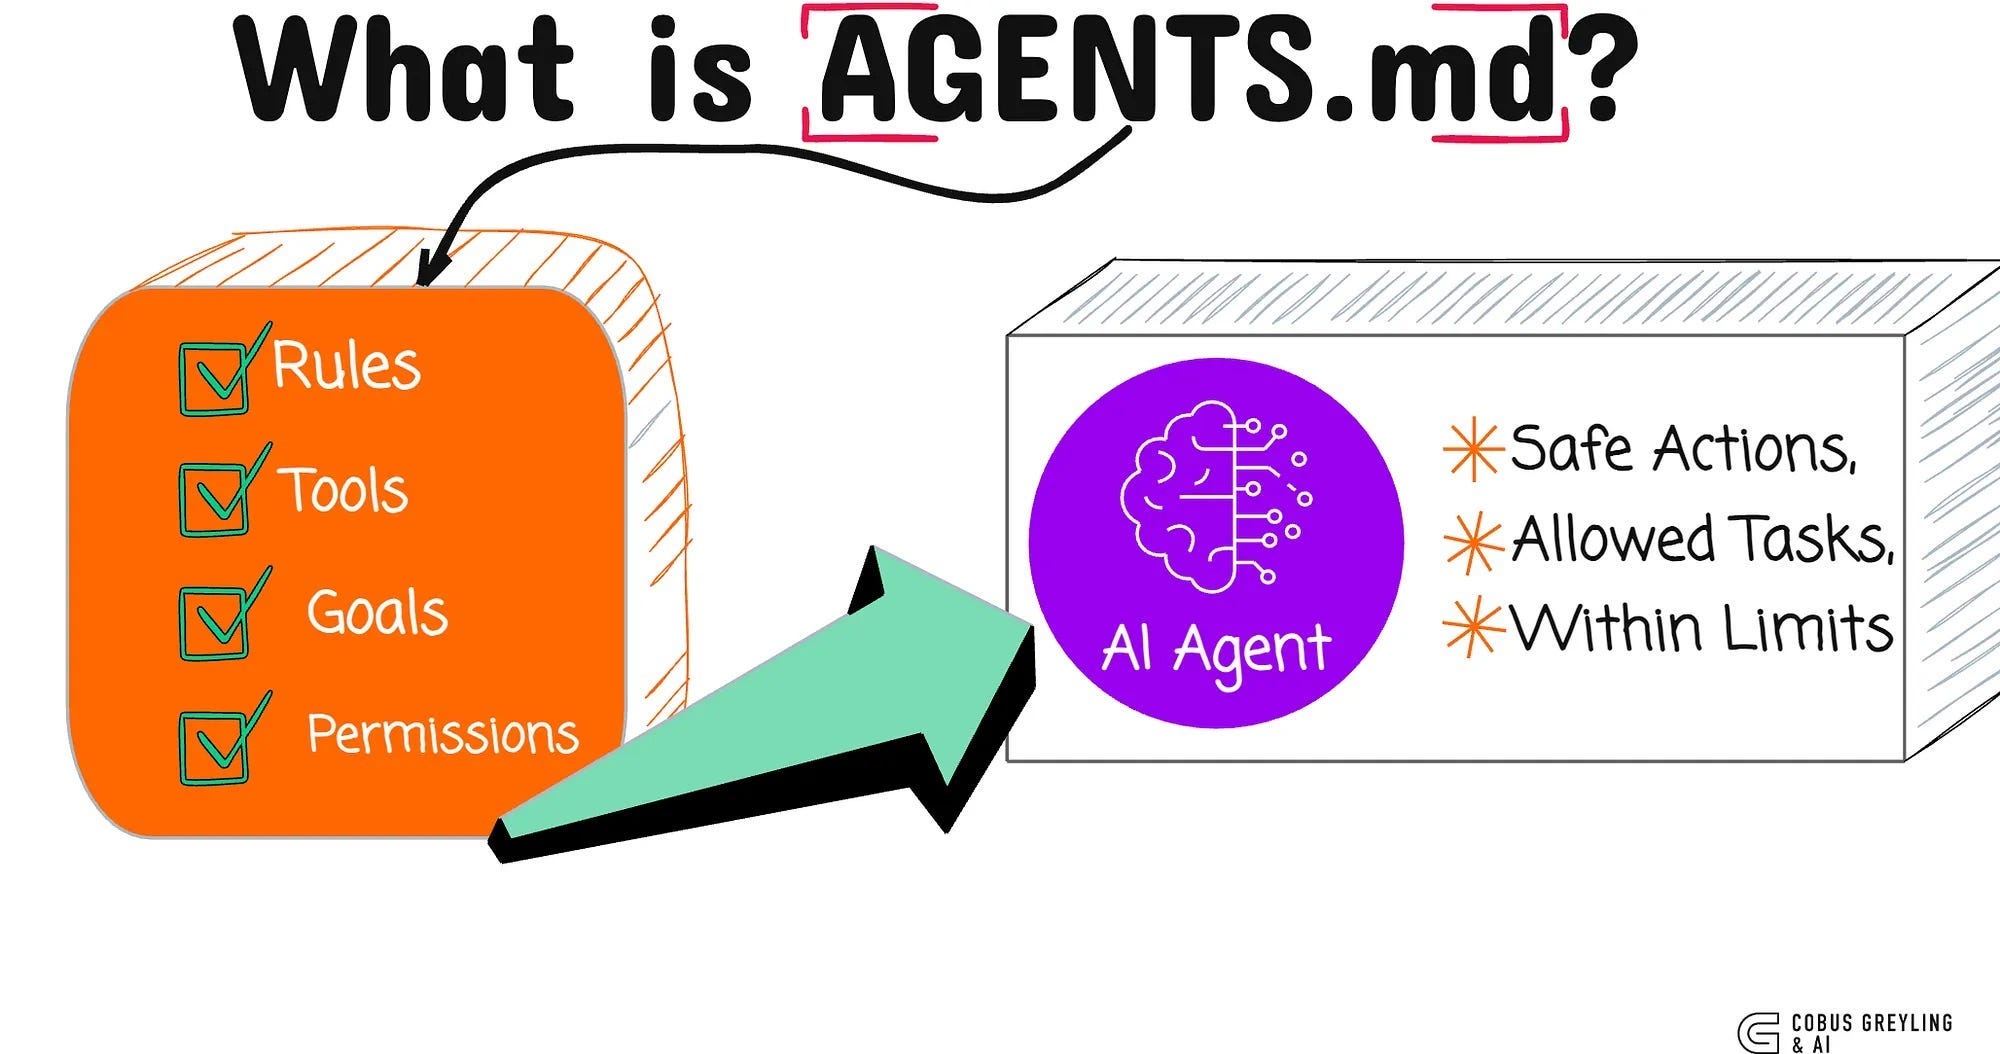
`CLAUDE.md` or `SKILL.md` is not documentation about the system.
It is the system.
The behaviour of the agent is whatever the markdown says it is.
Optimise for legibility, not cleverness.
The same file is read by your model, your colleagues, your future self…
And any agent that walks into the repository cold.
Plain headers and clear description beat dense YAML every time.
Quiet layer
The reason this shift is quiet is that markdown does not feel like a technology. It feels like writing.
Nobody announces a new markdown framework.
There is no markdown conference.
There is no markdown ecosystem to evangelise. It is just text with three or four conventions on top.
That is exactly why it wins.
The PSTN won the voice layer because it was already there.
The CLI won the tool layer because it was already there.
The terminal won the interface layer because it was already there.
Markdown is winning the mediation layer for the same reason.
It was already there , sitting in every README, every wiki, every Stack Overflow answer the model trained on, waiting for the moment when the format that humans and models both spoke fluently became the most valuable real estate in the stack.
The mediation layer is consolidating…onto the format that was always going to win once the consumer of the file became something that could read.

Backstory
While writing this post, I have some doubts about my premise…
Because modern LLMs can handle JSON, YAML, XML, or strict schemas reliably.
Especially with JSON mode, few-shot examples, or tool calling)
Models don’t need Markdown.
But I guess the points I’m trying to make make is…
Markdown has a perspective and reduced complexity.
Schemas create a split where humans fight syntax/indentation/validation, models get easy parsing.
Markdown collapses this, legible to both without ceremony.
It’s lower friction for iteration, collaboration, version control in Git, and onboarding (colleagues or new agents).
Also, token efficiency and native feel.
Markdown often uses fewer tokens than JSON (15–38% savings reported in some benchmarks) and requires less translation effort from the model.
For agent design, I think there are practical implications…
Start with the Markdown a human would write to brief a teammate.
Add validation at the edges rather than forcing everything through rigid schemas centrally.
This optimises for legibility over cleverness.
But, it’s not always Markdown, some push HTML for richer outputs (interactivity, diagrams) in certain agent loops.
But seemingly Markdown dominates configs, instructions, and knowledge because it’s lightweight and universal.
Chief AI Evangelist @ Kore.ai | I’m passionate about exploring the intersection of AI and language. From Language Models, AI Agents to Agentic Applications, Development Frameworks & Data-Centric Productivity Tools, I share insights and ideas on how these technologies are shaping the future.
